
Vision for Autonomous Exploration Robots
Multimodal perception that lets robots navigate unknown terrain safely.
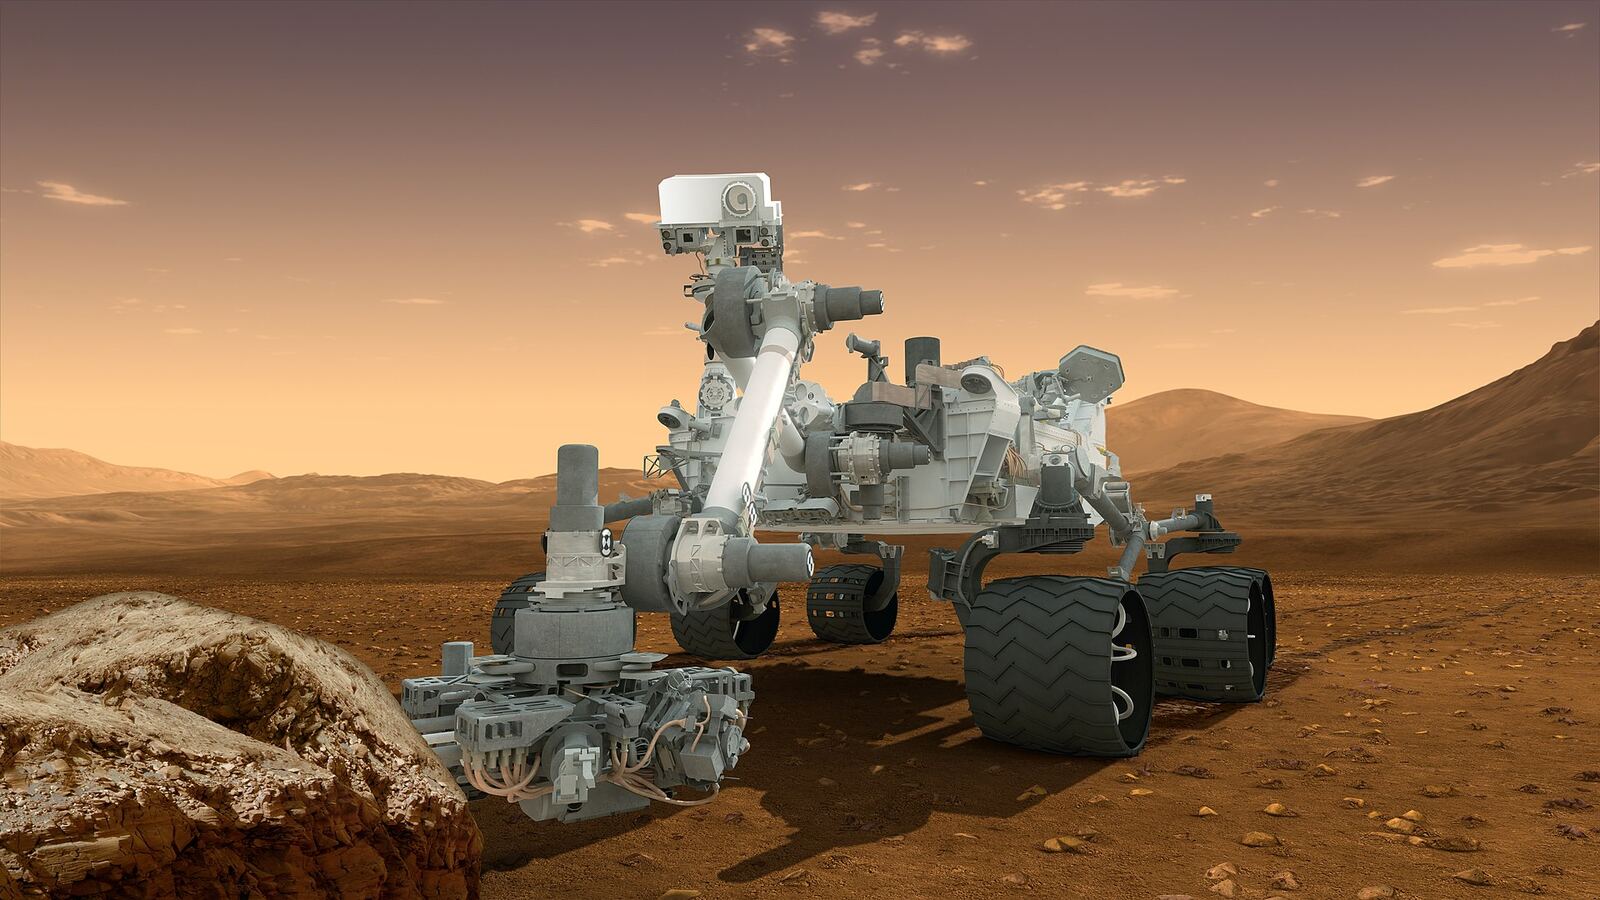
- Period
- January 2024 - present
- Funding
- Example Research Fund, grant EX-2024-017
- Members
- Lê Thu Hà, Nguyễn Bảo Châu, Trần Minh Khoa
Goals
Build a perception stack that lets autonomous robots estimate depth, segment terrain and follow natural-language instructions with little labelled data.
Approach
Self-supervised learning from image and LiDAR sequences, combined with a multimodal model that grounds instructions in observations.
Results
Two published papers: Self-Supervised Depth Estimation for Planetary Terrain and Multimodal Grounding of Natural-Language Instructions for Mobile Robots.
- computer vision
- autonomous robots